There is a type of board game that becomes genuinely tense around move forty, when one player has quietly acquired every property on one side of the board and you suddenly realise you have nowhere left to go. Not just a few squares — all of them. The orange ones, the red ones, the dark blue ones. Hotels on the lot. You are still holding your little pewter iron, convinced the dice will save you, right up until they don't. That feeling — the specific cold draught of a single point of failure revealing itself — visited a lot of businesses last Thursday, and it had nothing to do with a board game.
Which brings me, against all odds, to Microsoft's network infrastructure team and what they were doing on the afternoon of 12 November 2026. Finnwood's position on this is plain and we are not softening it: if your business cannot communicate, cannot invoice, cannot hold meetings, and cannot access files for a full working day because one supplier had a bad afternoon, that is not a technology problem you wandered into — it is a risk management decision you made without realising it. This week clarified the cost of that decision in unusually large numbers.
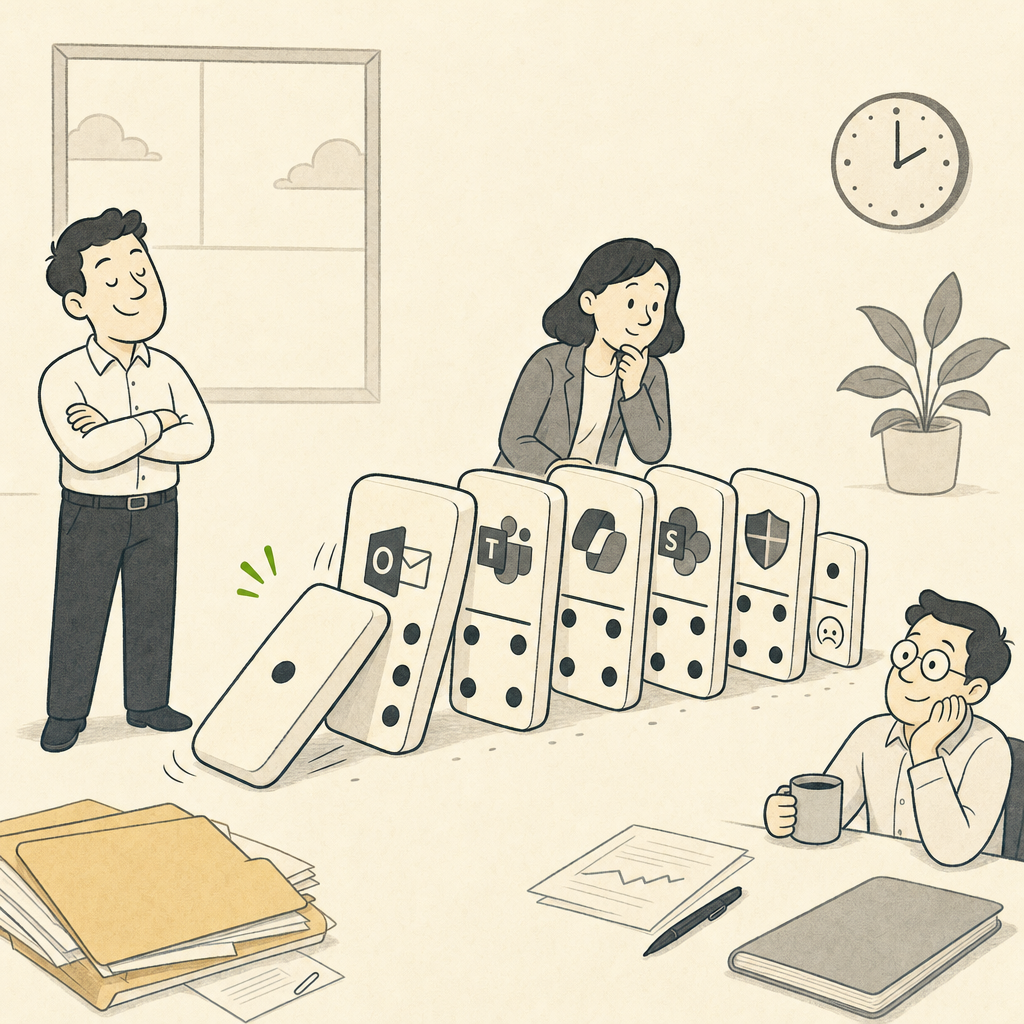
An issue linked to an earlier network-capacity upgrade surfaced after a more recent network change, triggering the outage on Thursday, 12 November 2026. Not a cyberattack. Not ransomware. Not a teenager in a basement — Microsoft itself confirmed that the widespread outage affecting its enterprise software products was not the result of a cyberattack. It was their own engineers, doing what engineers do — improving something — and Microsoft attributed the problem to elevated load across multiple regions, explaining that the load did not come from more traffic, but from a number of servers that had become unexpectedly unavailable, leaving the rest to carry the work. The remaining servers, now doing the work of several dead colleagues, buckled. This is what engineers call a cascade failure. The rest of us call it watching a Jenga tower fall in slow motion from the other side of a glass door, unable to knock.
At the core was Exchange Online, the email service behind Outlook for most organisations. Because so many Microsoft 365 services depend on Exchange Online, the impact quickly spread to Teams, SharePoint, Copilot, and Microsoft Defender. That is worth sitting with for a moment. One service goes down, and it takes email, video meetings, file sharing, the AI assistant, and the security layer with it — like watching a dog operate a revolving door, except the dog weighs $3 trillion and the door is your entire working day. The outage hit Outlook, Teams, SharePoint, Copilot, and Defender in at least 74 countries. At the peak on Thursday evening, Downdetector logged nearly 140,000 reports for Outlook alone. Microsoft said on Saturday 14 November that it had fixed the underlying issue and restored the last regions — meaning the outage ran, in total, the better part of 38 hours across two working days.
The bill, as far as anyone can estimate it, is extraordinary. Michigan-based think tank Anderson Economic Group calculated that the cost of lost productivity from Teams and Outlook going down could approach $7 billion. Anderson's president Patrick Anderson told CNN that while the majority of the estimated 430 million Microsoft users will see this outage as an annoyance that can be worked around, there could be genuine economic loss for as many as 26 million users on Thursday and 51 million users on Friday. Experts in Australia warned that the outage could cost billions of dollars to businesses there, with small businesses identified as the hardest hit. Small businesses. Not the enterprise with a forty-person IT department and a secondary data centre in Frankfurt. The firm of twelve people in Harrogate whose entire client communications run through one Microsoft tenant. Them.
And here is the part that should give every business owner pause: during the outage, Microsoft Defender's Safe Links may have been unable to verify URLs in Outlook and Teams — when the platform failed, the security controls built on top of it failed with it. So for those 38 hours, some firms were not just unable to work. They were also less protected, running without their usual scrutiny on incoming links, in a week when — as reliably happens after every major outage — the disruption sparked rampant speculation that Microsoft may have been hacked, and bad actors look to exploit that confusion. The ladder your business stands on and the safety net beneath it were, briefly, the same ladder.
The fix is not dramatic and it is not expensive. It is not a question of abandoning Microsoft — 365 remains genuinely good software and we say so plainly. The question is what happens on day two. Some organisations barely missed a beat, connecting with colleagues via Slack, phone, and even the old-fashioned way: in person. Those firms had a lightweight fallback — a secondary channel, even a WhatsApp group for urgent client contact, an IMAP account on a different provider for critical correspondence — and they used it. That is the difference between a bad afternoon and a lost contract. It is not belt-and-braces IT. It is what a sensible person does when they notice that every property on one side of the board has the same owner.
Which brings us back to the board game and the pewter iron. The player who buys everything wins a lot — until the moment they go offline for 38 hours and everyone else is left standing on their squares with nowhere to go. If last Thursday found your business in that position — inbox dark, Teams silent, Copilot staring blankly like a kettle that's decided this is its moment — then come and have a conversation with us. We will help you work out what a sensible backup communications route looks like for a firm your size, what it costs (usually: very little), and how quickly it can be ready. You can reach us by email. Or, if the irony of that is too much this week, by phone.